Paper Reports
Plain-language walkthroughs of papers from our group — what problem the paper attacks, how the system works, and what the numbers actually say. Each report links back to the paper itself.
2026 2 reports
SC '26
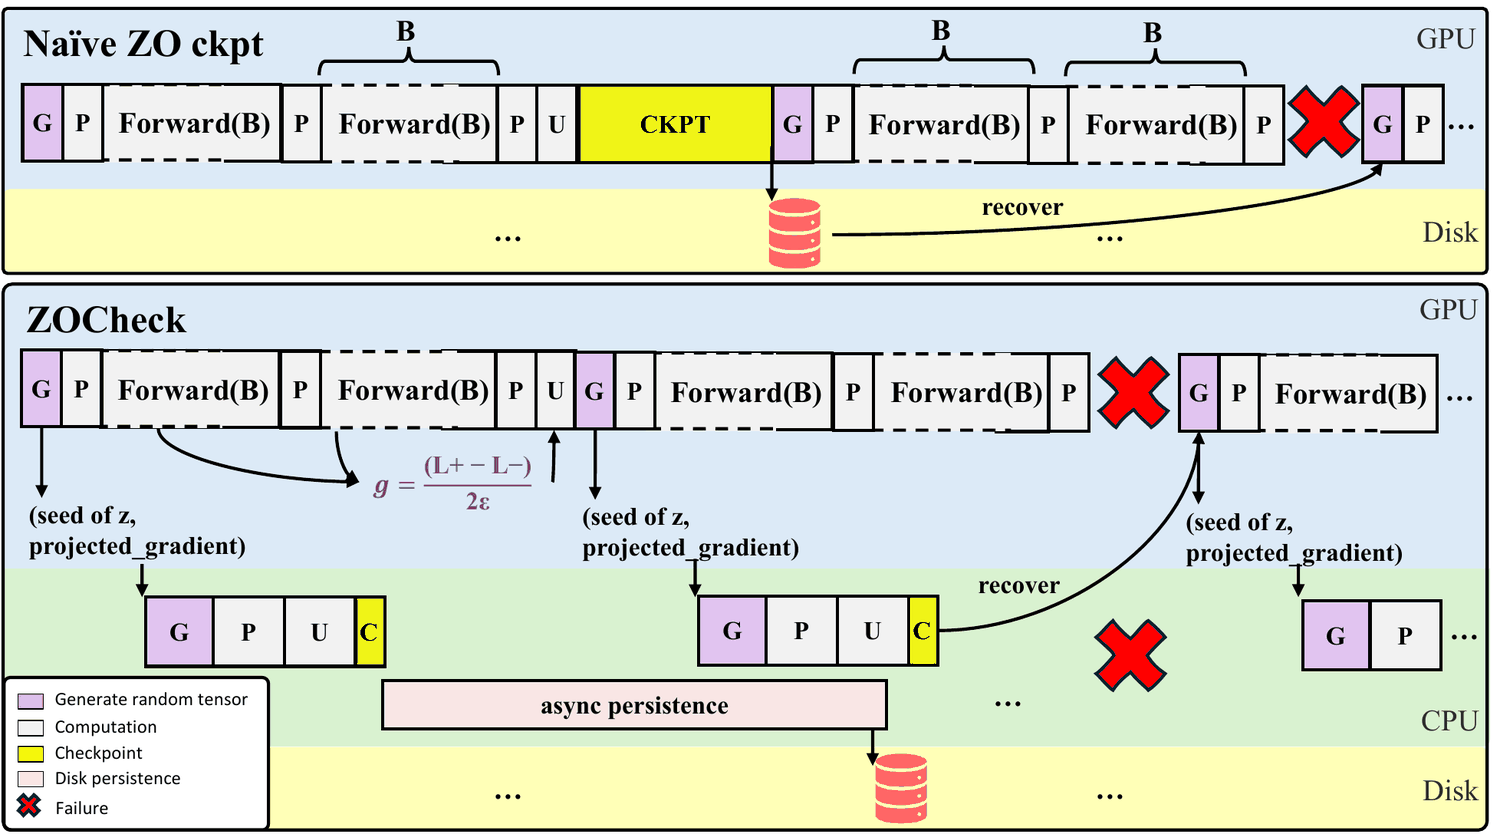
ZOCheck: CPU-Shadow Checkpointing for Zeroth-Order LLM Fine-Tuning
A zeroth-order training step is a seed and a scalar. Log those, let a CPU shadow replay them, and checkpointing costs almost nothing while recovery is bit-for-bit exact.
219.7× lower checkpoint overhead than asynchronous full-state checkpointing21.3× less end-to-end wasted time on Qwen3-8B across MTBFs of 3–15 h1.55× faster recovery than async checkpointing every 7 steps; 586× vs. log-only
Cluster '26
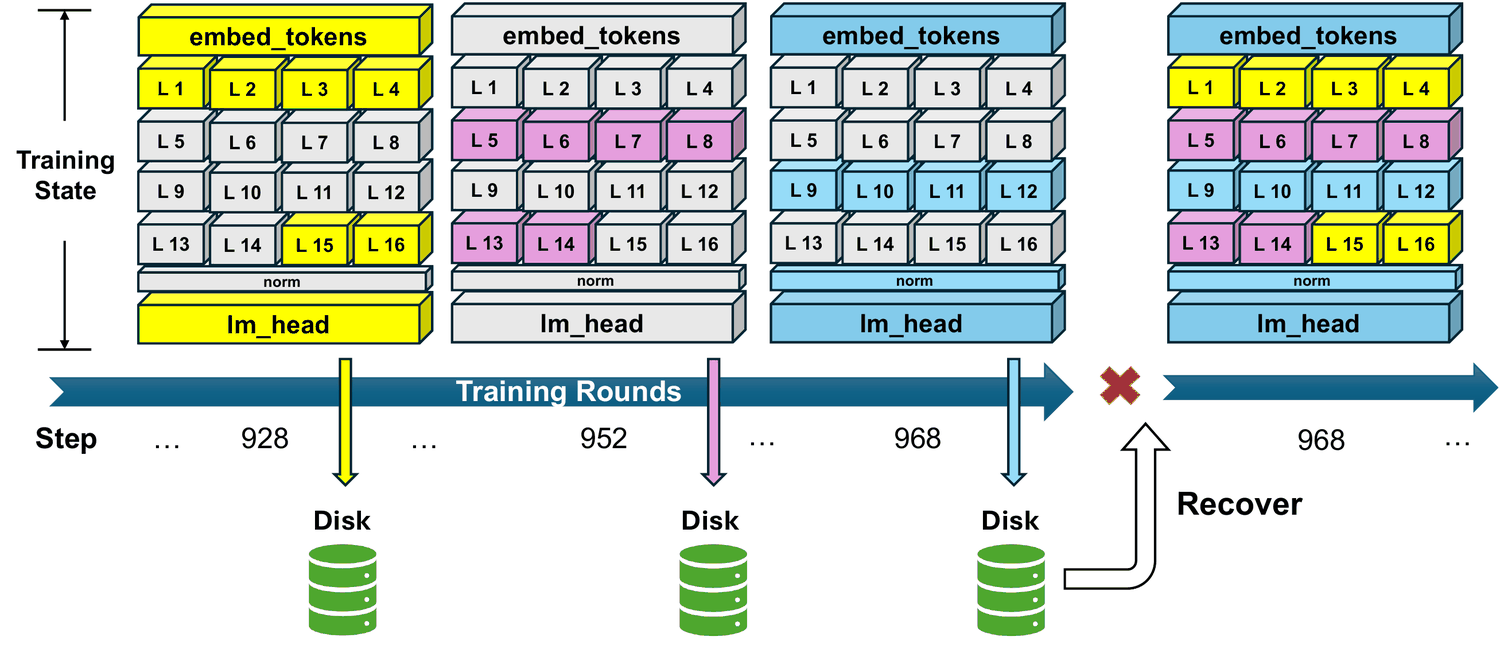
LayerCheck: Adaptive Layer-wise Checkpointing for Large Language Model Post-training
Save only the layers that changed, and rebuild the rest at recovery — 22.6× smaller checkpoints without changing what the model learns.
22.6× smaller total checkpoint storage than LowDiff0.54% max loss deviation after recovery, within training noise3.4× faster recovery at matched restart freshness
2025 1 report
SC '25
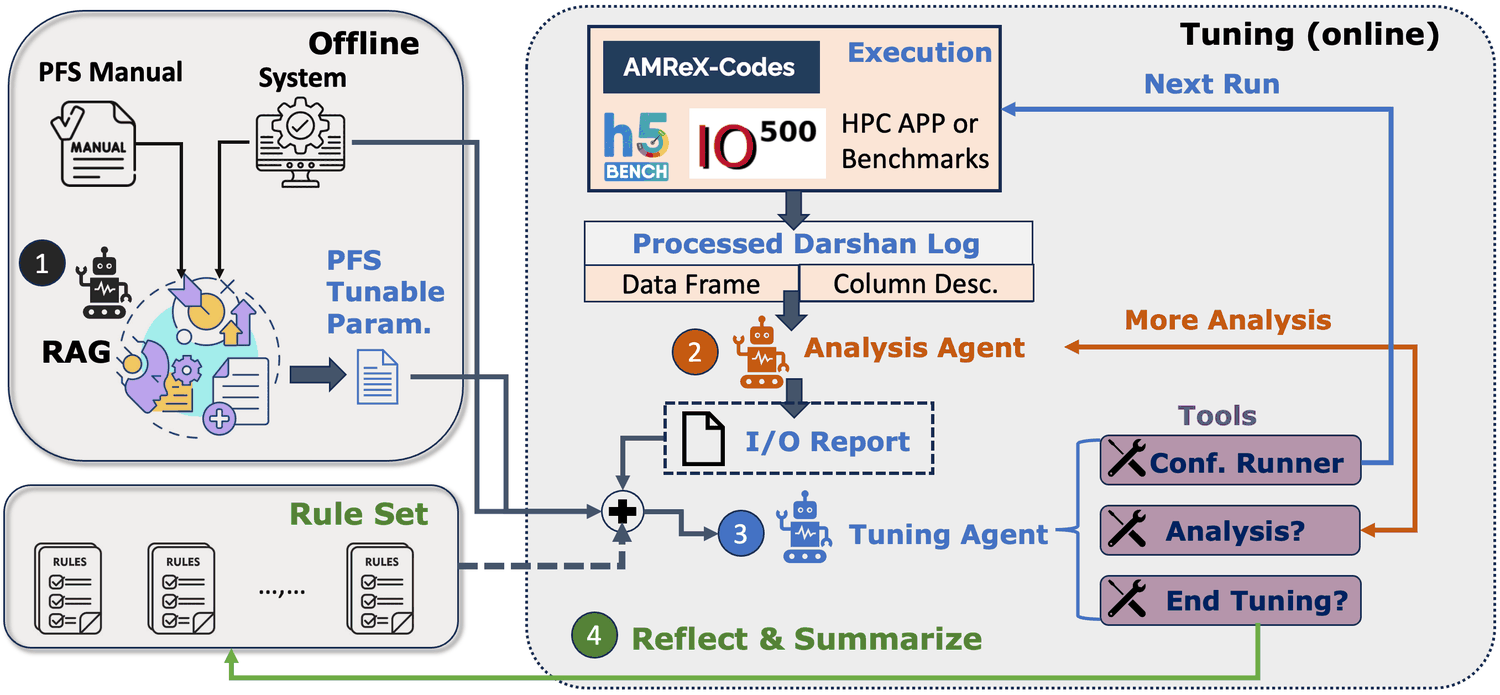
STELLAR: Storage Tuning Engine Leveraging LLM Autonomous Reasoning for HPC Parallel File Systems
An agentic LLM tuner that reaches near-expert Lustre configurations in five runs instead of thousands.
7.8× peak speedup over default Lustre settings≤ 5 configurations tried per tuning run13 parameters kept, out of 159+ Lustre exposes